Case study · Corporate intelligence · Private AI
A private, self-hosted AI assistant for a corporate intelligence firm, designed so confidential research never reaches a public AI service
A London investigations firm wanted the convenience of ChatGPT-style assistants for its analysts without sending client material to any outside AI provider. Ethora designed a single-tenant AI chat system with an open-weight language model on the firm’s own GPU, either on a dedicated server in a London cloud region or on a workstation in its office.
By the numbers
The project at a glance
Zero
public AI services in the path: prompts, documents and answers stay on the firm’s own server
2
hosting routes designed: a dedicated GPU server in a London cloud region, or a GPU workstation in the office
1 day
from the first call to a written proposal with hardware sizing guidance
4
settings to point Ethora’s AI service at a local model today, in our official Ollama example
A proposal, not a live deployment. This page describes the solution we designed and proposed in April 2026. The firm reviewed it and decided not to run a private AI model at that time. We publish it because the requirements come up again and again in legal, financial and investigative work, and because Ethora supports this setup today, now with self-install options as well as a managed server.
Overview
An AI assistant for work that cannot leave the building
The firm is a London-based corporate intelligence and investigations company. A team of around a dozen analysts researches companies, people and transactions for law firms, investors and financial institutions, often on deals and disputes where confidentiality is the whole product. The firm is not named here.
The challenge. The analysts already used public AI assistants such as ChatGPT, Claude and Perplexity for general work. They could not use them for the work that matters most: analysing confidential client material and the firm’s own research databases. They wanted the same kind of assistant, but on a system where the data stays on a server only the firm uses, no AI provider sees it or trains on it, and nothing can leak to another customer. They did not want to run their own infrastructure, and they wanted to know how such a server is protected against attack.
How they found us. The firm found Ethora through a ChatGPT recommendation and booked a call through our website. We held the call on 1 April 2026 and sent a written proposal, a sizing guide and a video demo of a branded Ethora AI workspace the next day.
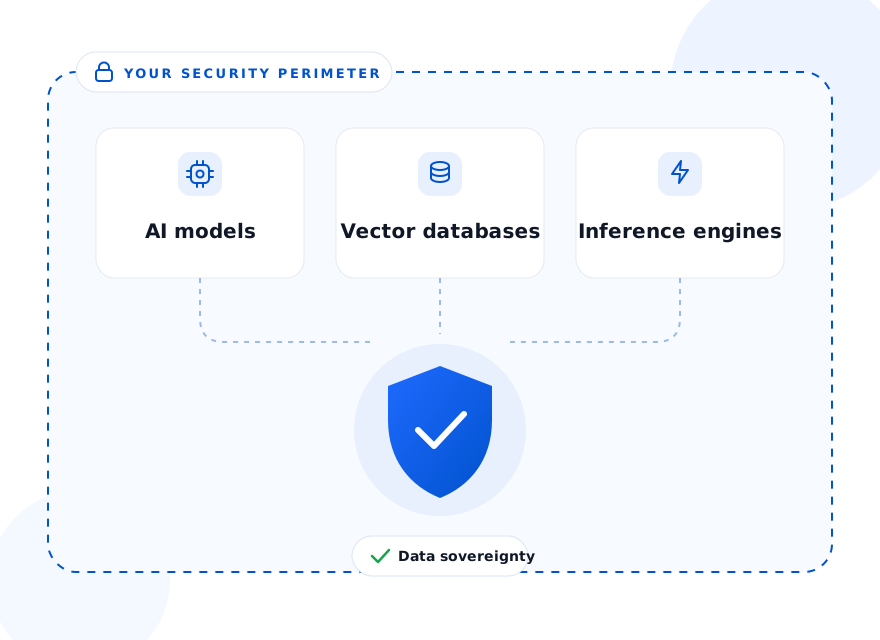
The approach. Ethora’s self-hosted LLM and AI agent stack, on a dedicated, single-tenant server: the web app, chat server, AI agents and document search from Ethora, and an open-weight language model served on a GPU next to it. Everything the analysts type, upload or get back stays inside that one environment.
The AI workspace
What the analysts would work in
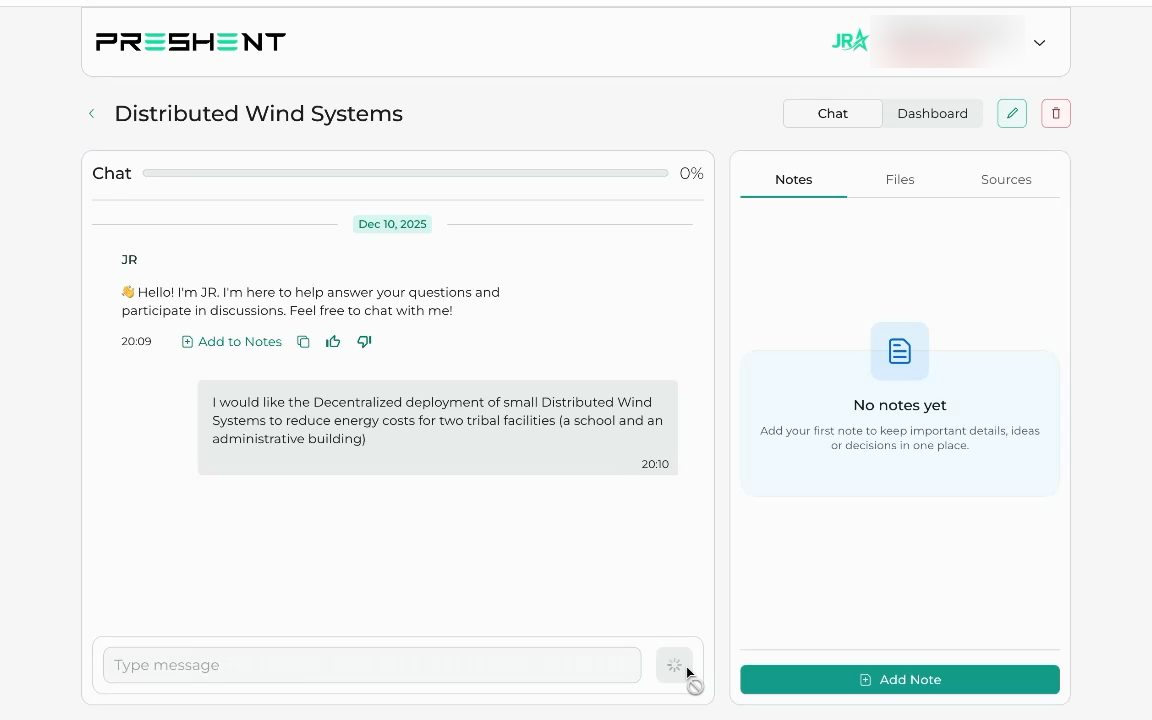
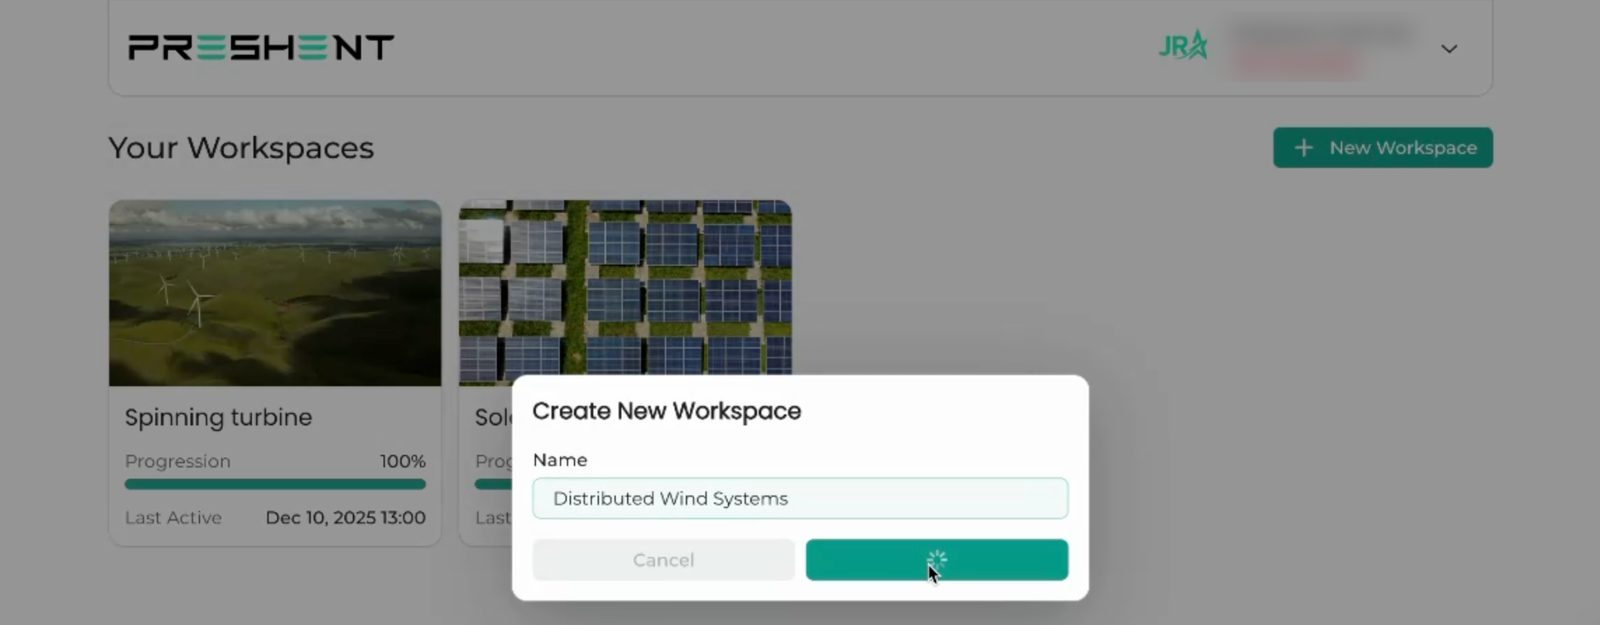
The proposal showed the firm the Ethora AI workspace as we had already set it up for another customer: Preshent, a US energy-project platform, whose assistant is called JR. The firm’s version would carry its own logo, colours and agent name.
Each piece of work gets its own workspace. Inside it, people chat with the AI agent on their own or as a group, and keep notes next to the conversation: one click adds a useful answer to the notes. Files hold the documents for that piece of work, and sources feed the agent new material automatically. For an investigations firm, a workspace maps naturally onto a client engagement, with only that team as members.
Requirements
What the firm needed, and how Ethora meets it
Each requirement is tagged by where it was covered in the April 2026 proposal, and where the capability is part of the Ethora platform today.
No confidential data sent to public AI services
The language model is an open-weight model running on the firm’s own GPU, not a call to an outside AI API. Ethora’s AI service talks to any OpenAI-compatible endpoint, such as Ollama or vLLM, so the model server sits next to the chat server in the same private environment. No provider sees the prompts, and nothing is used to train anyone’s model.
One tenant: the firm’s data never shares a server
A dedicated, single-tenant server holds the chat history, documents, search index and model. There are no other customers on it, so data cannot leak to another tenant by mistake or by misconfiguration. The firm can choose the region and availability zone, and keep everything in the UK.
No infrastructure team needed
The proposal was a managed server: Ethora installs, monitors and updates it under an SLA covering uptime, phone and ticket support, on-site visits in London and security updates. Firms with their own IT team can now also install Ethora themselves with Docker Compose, a Helm chart or a cloud marketplace image (see Get Ethora) and point it at their own model server.
Feels like the assistants analysts already use
Analysts work in workspaces: chat with an AI agent on their own or with colleagues, keep notes next to the conversation, and attach the files for that piece of work. Each agent has its own instructions and its own knowledge: files uploaded to it, and pages from websites it crawls, searched by keyword and by meaning so answers come from the firm’s own material. Agents can keep notes about a conversation over time, and each one can use a different model from the same model server.
Engagements kept apart
Investigations for different clients must not mix. A workspace per engagement, with only the analysts on that case as members and an agent whose knowledge holds only that case’s documents, keeps material separate; files in a room are only available to its members. For a harder wall, separate engagements can run as separate Ethora Apps, each an isolated container with its own users, files and chats.
Familiar sign-in and the firm’s own look
Google sign-in is a built-in option the administrator switches on, and accounts can also be created from the firm’s own systems through the API, so staff never manage a separate password store. The administrator uploads the firm’s logo and sets its colours, and a white-label build can carry its own name.
A model sized to the team, not guessed
GPU size drives cost and depends on three things: how many analysts ask at the same time, how fast answers must come, and how much text each question carries. One or two people at a time who can wait a few seconds need far less than a whole team working at once with instant answers. Rather than guess, we proposed a test with the analysts on our demo server first, then a hardware recommendation from what they actually did.
Data that keeps the assistant current
New reports and files can be added to an agent’s knowledge through the API as they arrive, and a website crawler keeps public sources indexed. The proposal also covered connecting the firm’s file storage and, later, its CRM and other systems through Ethora’s API and agent tools.
Deployment
Everything in one private environment
The same stack runs in either hosting route: a dedicated GPU server in a London cloud region, or a GPU workstation in the firm’s office with access limited to the local network. See Get Ethora for every way to install it.
Where this stack runs
Hosting
Cloud GPU or a workstation in the office
The proposal set out both routes with their trade-offs, and suggested a hybrid path: start on a dedicated cloud GPU server, which is the most flexible, and move to hardware in the office once the right balance of speed and cost is known.
| Dedicated cloud GPU server | GPU workstation in the office | |
|---|---|---|
| Who runs it | Ethora hosts and maintains it in a London cloud region on the firm’s behalf | The firm buys an AI workstation; Ethora installs and configures the software and network |
| Network | Private server reached over encrypted connections | Can be limited to the office network, with no connection to the internet |
| Capacity | Start small and upgrade the GPU when needed; scale down or switch off out of hours | Fixed by the hardware; more capacity means another machine |
| Cost shape | Monthly, no upfront spend, higher over several years | Upfront purchase, lower over one to two years, the firm owns the hardware |
| Maintenance | No power, cooling or hardware to look after | The firm looks after the machine; Ethora supports the software |
An entry-level AI workstation, such as an NVIDIA DGX Spark class machine, suits light use. A team that wants fast answers while everyone works at once needs a larger GPU server, in the cloud or in a rack.
Security
Controls built into the design
Answering the firm’s question: how is a private AI server protected?
Isolation
One tenant per server, a chosen region and availability zone, and an office-only network option for the on-premise route.
Encryption
TLS in transit and encryption at rest for messages and files, on a server only the firm uses.
Account security
Two-step verification with an authenticator app, admin roles with clear permissions, and an audit trail of who did what.
Data control
Configurable retention, export and per-user erasure, so the firm decides how long client material is kept.
Since April 2026
What a firm like this gets from Ethora today
In April 2026 the only route was a server installed and run by our team. Since then, the pieces of this design have become standard and documented:
- Install it yourself. Ethora runs on any Docker host with Docker Compose, on Kubernetes with a Helm chart, and from cloud marketplace images, alongside the managed dedicated server. All the options are on Get Ethora.
- A documented local model. Our official Ollama example switches the AI service to a local model with four settings (model server address, key, chat model and embedding model) and uses Postgres with pgvector for document search. On a small CPU-only test machine a 3B model answered short questions in 6 to 8 seconds; a GPU and a larger model are what a working team needs.
- Better agents. Agents now have their own instructions and memory, search their knowledge by keyword and by meaning, and show how healthy their knowledge index is, with a test chat that shows which sources an answer used.
- Stronger accounts. Two-step verification with an authenticator app, and a Users page that shows each person’s role and whether they have it switched on.
A fully offline (air-gapped) deployment is possible as an architecture: the self-hosted stack plus a local model, with no outbound connections. It is not a one-click installer, so we plan the image mirroring, certificates and update path with each customer.
The outcome
Designed, proposed, and ready for the next firm
The firm liked the proposal and took it to its team. In May 2026 it decided not to run a private AI model for the time being, and left the door open for later. The design stands: for a legal, financial or investigative team that wants AI assistants without handing client material to an AI provider, Ethora can run the whole system on a server the team controls, with the model next to it.
FAQ
What hardware do we need for a self-hosted LLM?
It depends on how many people ask at once, how fast answers must be and how much text each question carries. A small test machine can run a 3B model slowly; a team needs a GPU sized to its use. We recommend a short trial on our demo server before you choose hardware.
Can it run fully offline or air-gapped?
Architecturally, yes: the self-hosted stack is standard containers and the AI service works with a local model, so a deployment can run with no internet egress. Ethora does not ship a packaged air-gapped installer, so we plan image mirroring, certificates and updates with you.
Can we start in the cloud and move on-premise later?
Yes. The same stack runs on a dedicated cloud GPU server or on your own hardware, so you can start in the cloud, learn what speed and capacity you need, and move to an office server later.
Can we keep different clients’ material separate?
Yes. Use a workspace per engagement with only that team as members and an agent whose knowledge holds only that engagement’s documents. For a stricter separation, run engagements as separate Ethora Apps, each with its own users, files and chats.
More case studies

Energy: dedicated chat server, AI-agent rooms and a React Native app for a procurement platform
Preshent is a US platform for energy-project procurement with AI-driven decision support.
Ethora provides the conversation layer: a chat room per project workspace shared by people and the AI agent, a dedicated chat server in Preshent’s own cloud, push notifications and a React Native app.
- 1,130 chat rooms, one per workspace
- AI agent as a participant in every room
- Dedicated chat server, 99.99%+ uptime
Healthcare: HIPAA-compliant AI assistant (RAG) over a medical video library
Dr. Talks is one of the most prominent organizers of online healthcare conferences and summits.
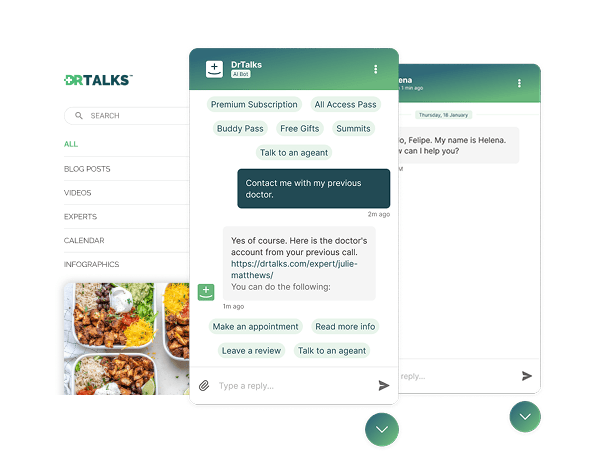
Ethora enabled them to create a context-aware AI-powered chatbot to help users navigate thousands of pages of medical content, correctly referencing pages, authors, videos and timestamps. 100% secure and HIPAA-compliant.
This assistant enhances user experience by simplifying interaction with the platform and reducing search time.
- 1000+ summits indexed by AI bot
- Instant user engagement
- Vector embeddings enable intelligent domain expert AI responses
Healthcare: self-hosted patient messaging for a multi-clinic digital health platform in Canada
VITALL is a Canadian digital health platform used by hospitals, clinics and private practices.
Ethora runs as a self-hosted chat server in VITALL’s own AWS account in Canada, with one isolated tenant per clinic, chat in the practitioner portal and in native iOS, Android and React Native patient apps.
Users, rooms and clinics are provisioned by VITALL’s backend through the Ethora API.
- Self-hosted in the customer’s AWS account in Canada
- One isolated tenant per clinic, created by API
- Web portal, iOS, Android and React Native SDKs
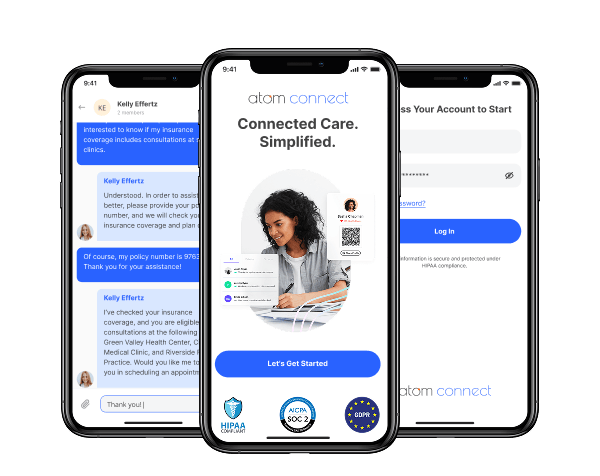

Insurance: in-app chat for a workers’ comp health insurance provider (HIPAA compliant)
Atom Advantage provides workers’ compensation and health insurance solutions in the United States.
On Ethora they built Atom Connect: secure, case-based chat between injured workers, nurses and case managers, embedded in their claims portal and a white-label mobile app. HIPAA and SOC 2 compatible.
Less manual work for case managers and a better experience for injured workers.
- Chat embedded in the case managers’ web portal
- White-label iOS and Android app for injured workers
- One secure room per claim, created automatically by API
Communities: fan chat app with second-screen rooms and digital collectibles
A cross-platform social app uniting the automotive community around racing events.
Fan rooms for teams and drivers, second-screen events, and collectibles handed out and traded through chat bots.
- Cross-platform iOS and Android app
- Fan rooms and second-screen events
- Collectibles distributed in chat
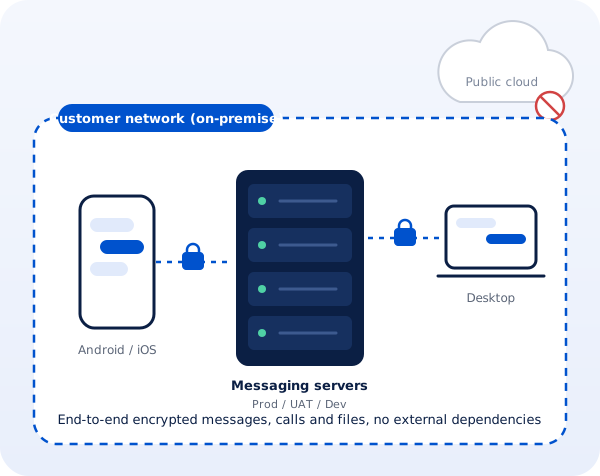
Defence: on-premise, end-to-end encrypted messaging for a European defence prime
An EU-based defence and aerospace prime, under NDA.
Ethora Professional Services built a fully on-premise, end-to-end encrypted messaging system with branded mobile and desktop clients, an offline build chain and no dependency on public cloud services.
- On-premise, air-gapped deployment
- End-to-end encrypted messages, files and calls
- Branded Android, iOS and desktop clients
Want AI assistants without handing client data to an AI provider?
A private Ethora server with a local model, run by us or installed by your team, in the cloud or in your office.